yolo v5 、ffmpge、nginx 视频检测
一、ffmpeg 下载
windows: https://www.gyan.dev/ffmpeg/builds/
ubuntu: https://github.com/BtbN/FFmpeg-Builds/releases
ffmpeg-master-latest-linux64-gpl.tar.xz
#新建ffmpeg 文件夹 更改为777 的权限
#解压即可
tar -xf ffmpeg-master-latest-linux64-gpl.tar.xz -C /usr/local/safeware/ffmpeg/ffmpeg --strip-components=1
#检测是否安装好
./ffmpeg -version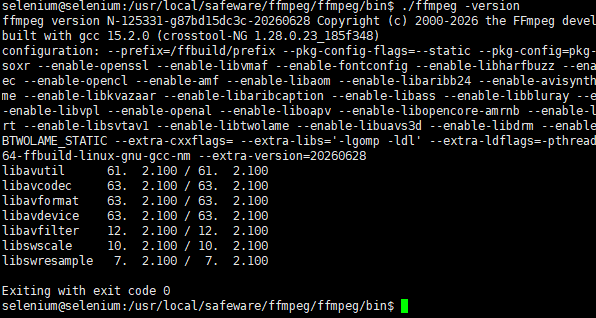
二、yolov5 中主要代码
yoloV5的utils/ffmpeg/ffmpeg.py 中创建 ffmpeg.py
复制代码
# subprocess 模块允许我们启动一个新进程,并连接到它们的输入/输出/错误管道,从而获取返回值。
import subprocess
import os
import signal
class FFmpeg():
    #fps 帧率 video_size 视频尺寸 push_url 推流到的服务器
    def __init__(self, fps, video_size,push_url):
        # 创建FFmpeg命令行参数
        ffmpeg_cmd = ['F:/chen/ffmpeg-8.1.1-full_build/bin/ffmpeg.exe', #ffmpeg 所在目录
                      '-itsoffset', '15',
                      '-r', str(fps[0]),  # '24.0' #帧率
                      '-y',  # 覆盖已存在的文件
                      '-f', 'rawvideo',
                      '-pixel_format', 'bgr24',
                      '-thread_queue_size', '1024',
                      '-video_size', video_size,
                      '-i', '-',  # 从标准输入读取数据
                      '-c:v', 'libx264',
                      '-preset', 'ultrafast',
                      '-tune', 'zerolatency',
                      '-pix_fmt', 'yuv420p',
                      '-f', 'flv',

                      push_url]
        print('ffmpeg_cmd:', ffmpeg_cmd)
        # 启动 ffmpeg
        self.ffmepg_process = subprocess.Popen(ffmpeg_cmd, stdin=subprocess.PIPE)
    #开始推流
    def streamPush(self, frame):
        self.ffmepg_process.stdin.write(frame.tobytes())
        #self.ffmepg_process.stdin.write(frame)
    #停止
    def stopPush(self):
        os.kill(self.ffmepg_process.pid, signal.SIGINT)
        self.ffmepg_process.wait()
改造detect 支持视频检测和推流
创建(模板来自根目录下的 detect.py) myDetect.py
# 自定义调用检测

import base64
import os
import sys
import threading
from pathlib import Path

import cv2


import torch
import torch.backends.cudnn as cudnn
from ultralytics.utils.ops import scale_coords
from ultralytics.utils.plotting import Annotator, save_one_box, colors

from utils.ffmpeg.ffmpeg import FFmpeg


FILE = Path(__file__).resolve()
ROOT = FILE.parents[0]  # YOLOv5 root directory
if str(ROOT) not in sys.path:
    sys.path.append(str(ROOT))  # add ROOT to PATH
ROOT = Path(os.path.relpath(ROOT, Path.cwd()))  # relative

from models.common import DetectMultiBackend
from utils.dataloaders import IMG_FORMATS, VID_FORMATS, LoadImages, LoadScreenshots, LoadStreams
from utils.general import (
    LOGGER,
    Profile,
    check_file,
    check_img_size,
    check_imshow,
    check_requirements,
    colorstr,
    cv2,
    increment_path,
    non_max_suppression,
    print_args,
    scale_boxes,
    strip_optimizer,
    xyxy2xywh,
)

from utils.torch_utils import select_device, time_sync


class MyDelect():

    def __init__(self, weights, source,returnStr):
        super().__init__()
        self.weights = weights
        self.source = source
        self.pushStream = None
        # 图片地址
        self.picPath = ""
        self.flag = False
        self.returnStr =returnStr

    # 真正运行的yolov5代码,加载模型
    @torch.no_grad()
    def loadModel(self, weights=ROOT / 'runs/train/exp39/weights/best.pt',  # 权重模型
                  source=ROOT / 'data/images/zidane.jpg',  # 需要检测的图片地址
                  imgsz=640,  # inference size (pixels) 检测裁剪大小
                  conf_thres=0.2,  # confidence threshold 预测概率大于0.25会被选中
                  iou_thres=0.45,  # NMS IOU threshold 保留的选中框数量
                  max_det=1000,  # maximum detections per image 检测个数
                  device='0',  # cuda device, i.e. 0 or 0,1,2,3 or cpu 检测的运算方式,cpu 还是GPU
                  view_img=False,  # show results 实时输出检测结果
                  save_txt=False,  # save results to *.txt 将检测结果保存
                  save_conf=False,  # save confidences in --save-txt labels 置信度保存,与txt一起使用
                  save_crop=False,  # save cropped prediction boxes 裁剪模型检测到的物体
                  nosave=False,  # do not save images/videos 是否保存预测结果
                  classes=None,  # filter by class: --class 0, or --class 0 2 3 类别数量
                  agnostic_nms=False,  # class-agnostic NMS 同一个物体检测为多个分类是否全显示选中框
                  augment=False,  # augmented inference 提高预测率
                  visualize=False,  # visualize features 保存特征文件,灰阶图
                  update=False,  # update all models
                  project=ROOT / 'runs/detect',  # save results to project/name 预测结果保存路径
                  name='exp',  # save results to project/name 保存的路径名字
                  exist_ok=False,  # existing project/name ok, do not increment 覆盖保存,检测结果都在相同文件夹下
                  line_thickness=1,  # bounding box thickness (pixels) #标注框细腻的
                  hide_labels=False,  # hide labels 是否隐藏标签
                  hide_conf=False,  # hide confidences 隐藏置信度
                  half=False,  # use FP16 half-precision inference 低精度预测,用于设备性能较弱的设备
                  dnn=False  # use OpenCV DNN for ONNX inference 使用openCV 的DNN进行ONNX推理
                  ):
        source = self.source
        weights = self.weights
        source = str(source)

        # 将source 转字符
        save_img = not nosave and not source.endswith('.txt')  # save inference images 保存检测结果
        is_file = Path(source).suffix[1:] in (IMG_FORMATS + VID_FORMATS)  # 判断sourc的格式,文件格式
        is_url = source.lower().startswith(('rtsp://', 'rtmp://', 'http://', 'https://'))  # 网络资源
        webcam = source.isnumeric() or source.endswith('.txt') or (is_url and not is_file)  # 当source 是视频将逐帧检测
        # 判断是否是视频

        # 将文件下载保存
        if is_url and is_file:
            source = check_file(source)  # download

        # Directories 保存文件夹,结果
        save_dir = increment_path(Path(project) / name, exist_ok=exist_ok)  # increment run
        (save_dir / 'labels' if save_txt else save_dir).mkdir(parents=True, exist_ok=True)  # make dir

        # Load model 模型加载
        device = select_device(device)
        # 视频及摄像头调用模型
        model = DetectMultiBackend(self.weights, device=device, dnn=dnn)
        stride, names, pt, jit, onnx = model.stride, model.names, model.pt, model.jit, model.onnx
        imgsz = [640, 640]  # 设置为数组
        imgsz = check_img_size(imgsz, s=stride)  # check image size

        # Half
        half &= pt and device.type != 'cpu'  # half precision only supported by PyTorch on CUDA
        if pt:
            model.model.half() if half else model.model.float()

        # Dataloader 加载资源
        if webcam:
            view_img = check_imshow()
            cudnn.benchmark = True  # set True to speed up constant image size inference
            # 调用摄像头
            dataset = LoadStreams(source, img_size=imgsz, stride=stride, auto=pt and not jit)
            bs = len(dataset)  # batch_size
        else:
            dataset = LoadImages(source, img_size=imgsz, stride=stride, auto=pt and not jit)
            bs = 1  # batch_size
        vid_path, vid_writer = [None] * bs, [None] * bs  # vid_path 和 vid_writer 分别是视频路径和视频编写器

        # Run inference
        if pt and device.type != 'cpu':
            model(torch.zeros(1, 3, *imgsz).to(device).type_as(next(model.model.parameters())))  # warmup
        dt, seen = [0.0, 0.0, 0.0], 0
        # 创建Ffmepg对象
        if (self.pushStream == None):
            videoSize = str(dataset.my_w) + "x"+str(dataset.my_h)
            self.pushStream = FFmpeg( dataset.fps,videoSize,"rtmp://192.168.2.136/live/test")
        for path, im, im0s, vid_cap, s in dataset:
            if (self.flag):
                if (self.source == '0'):
                    # 关闭摄像头
                    dataset.closeCamer()
                    return
                print("stop")
                return
            t1 = time_sync()
            im = torch.from_numpy(im).to(device)
            im = im.half() if half else im.float()  # uint8 to fp16/32
            im /= 255  # 0 - 255 to 0.0 - 1.0
            if len(im.shape) == 3:
                im = im[None]  # expand for batch dim
            t2 = time_sync()
            dt[0] += t2 - t1

            # Inference
            visualize = increment_path(save_dir / Path(path).stem, mkdir=True) if visualize else False
            pred = model(im, augment=augment, visualize=visualize)
            t3 = time_sync()
            dt[1] += t3 - t2

            # NMS
            pred = non_max_suppression(pred, conf_thres, iou_thres, classes, agnostic_nms, max_det=max_det)
            dt[2] += time_sync() - t3

            # Second-stage classifier (optional)
            # pred = utils.general.apply_classifier(pred, classifier_model, im, im0s)

            # Process predictions
            for i, det in enumerate(pred):  # per image
                seen += 1
                if webcam:  # batch_size >= 1
                    p, im0, frame = path[i], im0s[i].copy(), dataset.count
                    s += f'{i}: '
                else:
                    p, im0, frame = path, im0s.copy(), getattr(dataset, 'frame', 0)

                p = Path(p)  # to Path
                save_path = str(save_dir / p.name)  # im.jpg
                self.picPath = save_path
                txt_path = str(save_dir / 'labels' / p.stem) + (
                    '' if dataset.mode == 'image' else f'_{frame}')  # im.txt
                s += '%gx%g ' % im.shape[2:]  # print string
                gn = torch.tensor(im0.shape)[[1, 0, 1, 0]]  # normalization gain whwh
                imc = im0.copy() if save_crop else im0  # for save_crop
                annotator = Annotator(im0, line_width=line_thickness, example=str(names))
                if len(det):
                    count = 0#分类计数
                    # Rescale boxes from img_size to im0 size
                    det[:, :4] = scale_coords(im.shape[2:], det[:, :4], im0.shape).round()

                    # Print results
                    for c in det[:, -1].unique():
                        n = (det[:, -1] == c).sum()  # detections per class
                        s += f"{n} {names[int(c)]}{'s' * (n > 1)}, "  # add to string

                    # Write results
                    for *xyxy, conf, cls in reversed(det):
                        if save_txt:  # Write to file
                            xywh = (xyxy2xywh(torch.tensor(xyxy).view(1, 4)) / gn).view(-1).tolist()  # normalized xywh
                            line = (cls, *xywh, conf) if save_conf else (cls, *xywh)  # label format
                            with open(txt_path + '.txt', 'a') as f:
                                f.write(('%g ' * len(line)).rstrip() % line + '\n')
                                test = ('%g ' * len(line)).rstrip() % line + '\n'
                                # print(test.split()[len(test.split())-1])
                        if (cls == 0):
                            count = count + 1

                        if save_img or save_crop or view_img:  # Add bbox to image
                            c = int(cls)  # integer class
                            label = None if hide_labels else (names[c] if hide_conf else f'{names[c]} {conf:.2f}')
                            annotator.box_label(xyxy, label, color=colors(c, True))
                            if save_crop:
                                save_one_box(xyxy, imc, file=save_dir / 'crops' / names[c] / f'{p.stem}.jpg', BGR=True)

                # Print time (inference-only)
               # LOGGER.info(f'{s}Done. ({t3 - t2:.3f}s)')

                # Stream results
                im0 = annotator.result()
                if source.endswith("mp4"):
                    view_img = True
                # 打开视频播放窗口,推流到ffmpeg服务器
                if view_img:
                  #  text = 'person:%d ' % (count)
                   # cv2.putText(im0, text, (180, 50), cv2.FONT_HERSHEY_SIMPLEX, 2, (0, 0, 255), 5)
                    # 推流
                    self.pushStream.streamPush(im0)
                    # 打开播放窗口
                    cv2.imshow(str(p), im0)
                    cv2.waitKey(1)  # 1 millisecond

                # Save results (image with detections)
                if save_img:
                    if dataset.mode == 'image':
                        # 图片保存
                        cv2.imwrite(save_path, im0)


                    else:  # 'video' or 'stream'
                        # 视频
                        if vid_path[i] != save_path:  # new video
                            vid_path[i] = save_path
                            if isinstance(vid_writer[i], cv2.VideoWriter):
                                vid_writer[i].release()  # release previous video writer
                            if vid_cap:  # video
                                fps = vid_cap.get(cv2.CAP_PROP_FPS)
                                w = int(vid_cap.get(cv2.CAP_PROP_FRAME_WIDTH))
                                h = int(vid_cap.get(cv2.CAP_PROP_FRAME_HEIGHT))
                            else:  # stream
                                fps, w, h = 30, im0.shape[1], im0.shape[0]
                                save_path += '.mp4'

                            vid_writer[i] = cv2.VideoWriter(save_path, cv2.VideoWriter_fourcc(*'mp4v'), fps, (w, h))

                        vid_writer[i].write(im0)

        # Print results
        t = tuple(x / seen * 1E3 for x in dt)  # speeds per image
        LOGGER.info(f'Speed: %.1fms pre-process, %.1fms inference, %.1fms NMS per image at shape {(1, 3, *imgsz)}' % t)
        if save_txt or save_img:
            s = f"\n{len(list(save_dir.glob('labels/*.txt')))} labels saved to {save_dir / 'labels'}" if save_txt else ''
            LOGGER.info(f"Results saved to {colorstr('bold', save_dir)}{s}")
        if update:
            strip_optimizer(weights)  # update model (to fix SourceChangeWarning)

        return self.picPath

    # 视频
    def useYolo(self):
        if (self.flag == True):
            self.flag = False
        self.thread = threading.Thread(target=self.loadModel)
        self.thread.start()

    def useYoloImg(self):
        # 将图片转换成base64
        result = self.loadModel()
        with open(result, 'rb') as img:
            # 使用base64进行编码
            b64encode = base64.b64encode(img.read())
            s = b64encode.decode()
            b64_encode = 'data:image/jpeg;base64,%s' % s
            # 返回base64编码字符串
            return b64_encode

    def stopYolo(self):

        self.flag = True
        self.thread.join()
        self.pushStream.stopPush()
        print("Thread stopped")
测试代码 test.py
def test():
    myDetect = MyDelect("F:\\chen\\yolov5\\runs\\train\\exp3\\weights\\best.pt",
                        "http://60.10.139.113:8801/hls/13/index.m3u8","")
    myDetect.useYolo()

if __name__ == "__main__":
    test()
使用VLC进行串流播放,nginx串流地址: rtmp://192.168.2.136/live/test,结果如下
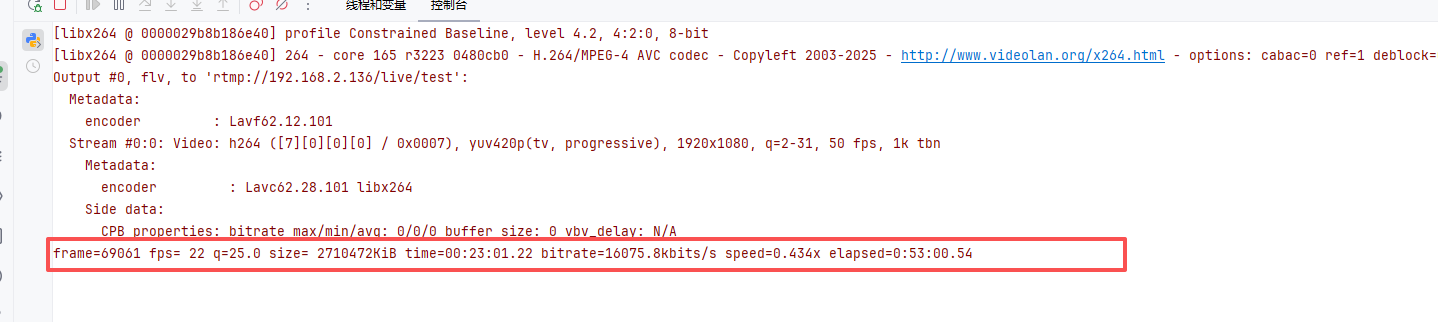
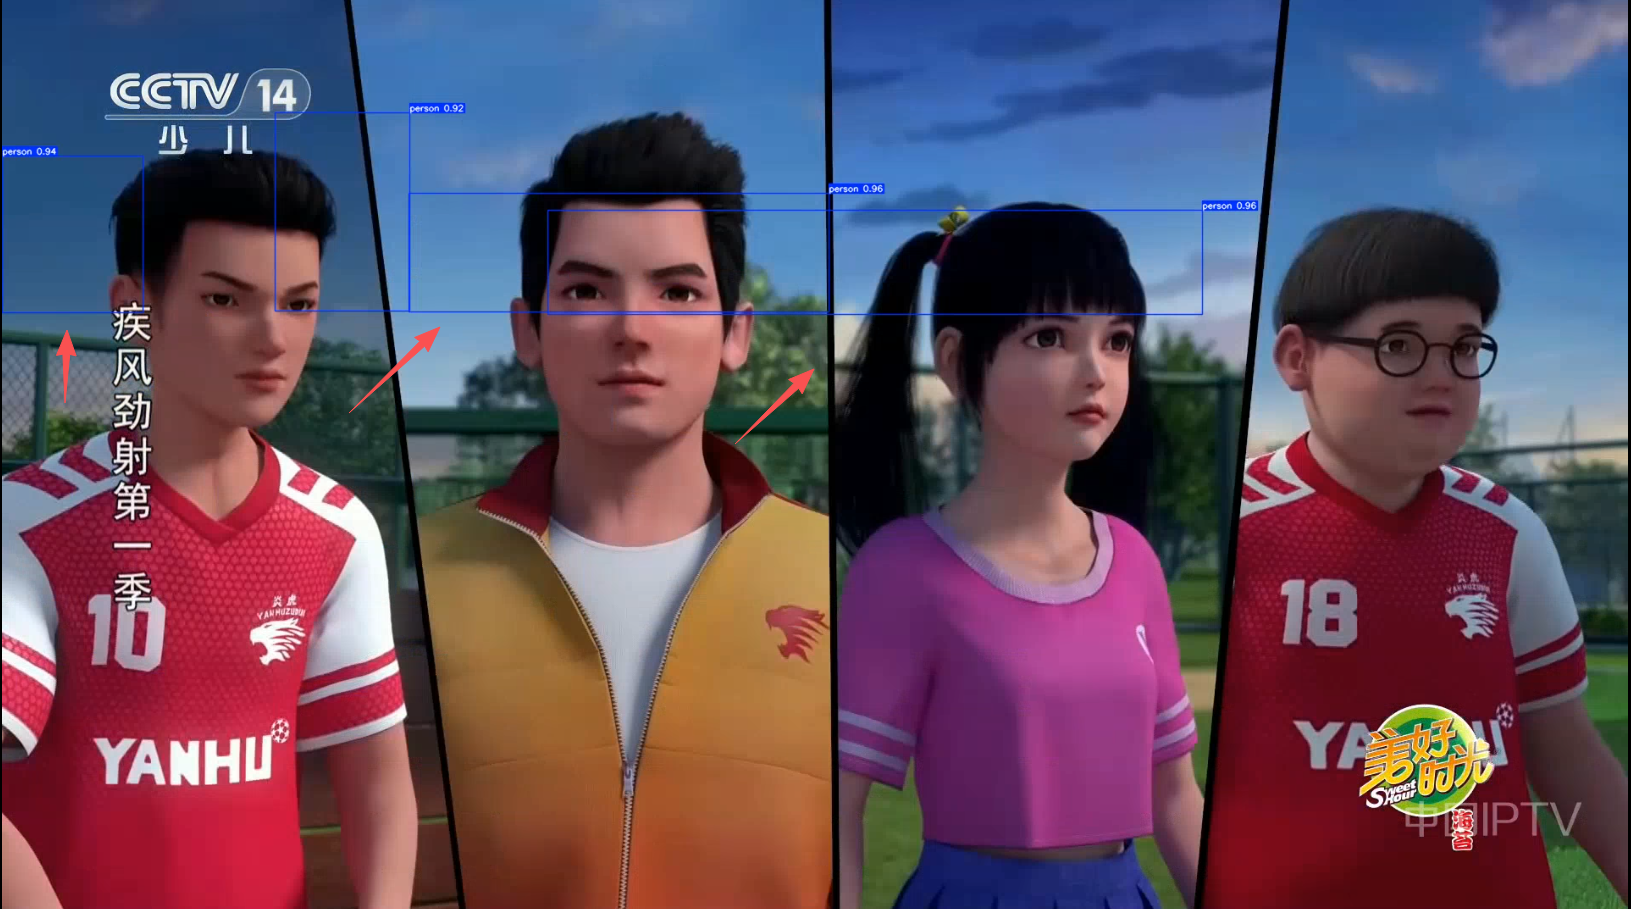
注:yolov5 是一帧一帧的检测修改的,所以需要将流修改后再推到推流服务器上,这里使用的是nginx搭建的推流服务器,搭建参考 :http://8.137.94.77:7090/archives/nginx-tui-liu-la-liu-fu-wu-qi
目前推流的视频在播放时存在卡顿的现象,需要进一步优化
可能是目前电脑配置不够(逐帧处理返回速度导致的)或者是ffmpeg推流配置没正确处理